GSP1298

Overview
Imagine you are a data engineer for Cymbal Gaming. You and the development team are building a new e-sports game, "Galactic Grand Prix." The game produces real-time data based on heads-up games between two players from different teams. For example, two players will compete in one event. A winner is determined, and then points are awarded to the winning player and team. You are tasked with building a solution to handle this streamed data, leveraging a Dataflow pipeline to ingest data from Pub/Sub, transform it using Python code, and store the results in BigQuery tables. These tables will then be used to visualize the results as player and team dashboards.
You have read that Pub/Sub, Dataflow, and BigQuery can be combined to build scalable, low-latency streaming data pipelines. In this lab, you ingest data from Pub/Sub, transform and aggregate streaming metrics using Python and Apache Beam running on Dataflow, and write results into BigQuery to power real-time player and team leaderboards.
When you start the lab, the environment will contain the resources shown in the following diagram.
By the end of the lab, you will have used the architecture to perform several tasks.
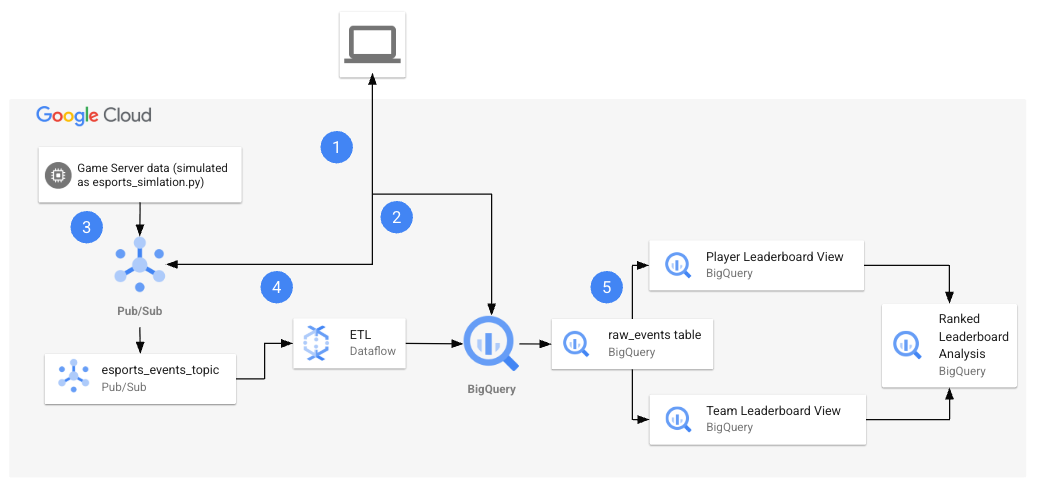
The following table provides a detailed explanation of each task in relation to the lab architecture.
| Numbered Task |
Detail |
| 1. |
Configure environment variables in Cloud Shell. |
| 2. |
Create the cloud resources:
You will use Cloud Shell commands to create the Pub/Sub topic and subscription, and the BigQuery dataset. |
| 3. |
Retrieve the Python files from the repo:
In this task, you retrieve the Python files from the repo and configure them for your project. |
| 4. |
Generate synthetic data and run the pipeline:
With the Python files configured for your project, you will then run the files to generate synthetic data and initiate the pipeline. The esports-simulation.py file uses Python to generate continuous Pub/Sub messages for game events. You can then run the esports-pipeline.py file. Running this file launches a Dataflow pipeline that ingests the messages, transform them, and record the results to the raw_events, player score updates and team score updates tables in BigQuery. |
| 5. |
Verify the results in BigQuery:
Now that you have consumed and transformed the data, and written the records to the tables in BigQuery, it is time to verify the results. You will run queries on each table to analyze and view the results. |
Objectives
In this lab, you learn how to:
- Configure environment variables.
- Create the cloud resources.
- Retrieve Python files from the repo and modify them for your project.
- Generate synthetic data and run the pipeline.
- Verify the results in BigQuery.
Finally, you will have time to reflect on what you have learned in this lab and consider how you could address your own use cases with streaming data, and answer questions in your Lab Journal.
Setup and requirements
Before you click the Start Lab button
Read these instructions. Labs are timed and you cannot pause them. The timer, which starts when you click Start Lab, shows how long Google Cloud resources are made available to you.
This hands-on lab lets you do the lab activities in a real cloud environment, not in a simulation or demo environment. It does so by giving you new, temporary credentials you use to sign in and access Google Cloud for the duration of the lab.
To complete this lab, you need:
- Access to a standard internet browser (Chrome browser recommended).
Note: Use an Incognito (recommended) or private browser window to run this lab. This prevents conflicts between your personal account and the student account, which may cause extra charges incurred to your personal account.
- Time to complete the lab—remember, once you start, you cannot pause a lab.
Note: Use only the student account for this lab. If you use a different Google Cloud account, you may incur charges to that account.
How to start your lab and sign in to the Google Cloud console
-
Click the Start Lab button. If you need to pay for the lab, a dialog opens for you to select your payment method.
On the right is the Lab setup and access panel with the following:
- The Open Google Cloud console button
- The temporary credentials (username and password) that you must use for this lab
- Other information, if needed, to step through this lab
Note that the lab timer is located near the top of the page, showing the remaining time.
-
Click Open Google Cloud console (or right-click and select Open Link in Incognito Window if you are running the Chrome browser).
The lab spins up resources, and then opens another tab that shows the Sign in page.
Tip: Arrange the tabs in separate windows, side-by-side.
Note: If you see the Choose an account dialog, click Use Another Account.
-
If necessary, copy the Username below and paste it into the Sign in dialog.
{{{user_0.username | "Username"}}}
You can also find the Username in the Lab setup and access panel.
-
Click Next.
-
Copy the Password below and paste it into the Welcome dialog.
{{{user_0.password | "Password"}}}
You can also find the Password in the Lab setup and access panel.
-
Click Next.
Important: You must use the credentials the lab provides you. Do not use your Google Cloud account credentials.
Note: Using your own Google Cloud account for this lab may incur extra charges.
-
Click through the subsequent pages:
- Accept the terms and conditions.
- Do not add recovery options or two-factor authentication (because this is a temporary account).
- Do not sign up for free trials.
After a few moments, the Google Cloud console opens in this tab.
Note: To access Google Cloud products and services, click the Navigation menu or type the service or product name in the Search field.

Task 1. Configure environment variables in Cloud Shell
In this task, you configure environment variables in Cloud Shell.
-
Open Cloud Shell.
-
You need to authorize use, as this is the first time you use Cloud Shell in this lab. To do this, click Authorize on the pop-up window.
-
Run the following commands.
export PROJECT_ID="{{{project_0.project_id|set at lab start}}}"
export REGION="{{{project_0.default_region|set at lab start}}}"
export BUCKET_NAME="{{{project_0.project_id|set at lab start}}}-bucket"
-
Run the commands below to confirm the variables are stored.
echo ${PROJECT_ID}
echo ${REGION}
echo ${BUCKET_NAME}
Task 2. Create the cloud resources
In this task, you will create the cloud resources including the Pub/Sub topic and subscription, and the BigQuery dataset using Cloud Shell.
Create the cloud resources
While remaining in Cloud Shell:
-
Run the following command to create the Pub/Sub topic.
gcloud pubsub topics create esports_events_topic
-
Run the following command to create the Pub/Sub subscription.
gcloud pubsub subscriptions create esports_events_topic-sub --topic=esports_events_topic
-
Run the following command to create the BigQuery dataset.
bq --location=US mk --dataset esports_analytics
Confirm creation of resources
-
At the top of the console, there is a search function. Enter Pub/Sub here, and click Pub/Sub from the options listed. You see Pub/Sub topics listed, including the esports_events_topic.
-
Click on esports_events_topic, which is the topic ID. You see the Subscriptions tab appear for the topic, and the esports_events_topic-sub subscription is listed. This confirms you successfully created the topic and the subscription.
-
Return to the search function at the top of the console. Enter BigQuery here, and click BigQuery from the options listed. You see the Welcome to BigQuery Studio page appears with a pop-up for Welcome to BigQuery in the Cloud Console.
-
Click Done.
-
Within the Explorer pane, expand your project.
-
Notice at the bottom of the list, you see the esports_analytics dataset. This confirms you successfully created the BigQuery dataset.
Click Check my progress to verify the objective.
Create the cloud resources
Task 3. Retrieve the Python files and configure them
In this task, you retrieve the Python pipeline files from Cloud Storage, review their structure and logic, configure the scripts with your lab project and bucket settings, and save a copy to your Cloud Storage bucket.
Retrieve the Python files
-
Return to Cloud Shell.
-
Run the following command to return to the home directory:
cd ~
-
Create the esports directory and navigate to it:
mkdir -p esports
cd esports
-
Retrieve the Python files using the wget commands below:
wget https://storage.googleapis.com/spls/gsp1298/esports-simulation.py
wget https://storage.googleapis.com/spls/gsp1298/esports-pipeline.py
You see confirmation in the terminal that both files have been downloaded.
Review the Python script architecture
Before executing the pipeline, review how each script functions:
-
esports-simulation.py:
- Simulates continuous real-time esports match events between competing teams (
team_alpha, team_bravo, team_charli, team_delta).
- Generates standard JSON event payloads including
match_start, player_elimination, and match_end.
- Uses the Google Cloud Pub/Sub Publisher Client (
google.cloud.pubsub_v1.PublisherClient) to publish serialized JSON events to the esports_events_topic topic.
-
esports-pipeline.py:
- Implements an Apache Beam streaming pipeline run by Google Cloud Dataflow.
- Consumes live JSON messages from the Pub/Sub subscription
esports_events_topic-sub.
- Deserializes each event, extracts match telemetry, computes sliding window aggregations for player and team score leaderboards, and streams the output directly into the BigQuery
esports_analytics dataset.
Configure the files for your project and bucket
You must configure the scripts with your project ID, region, and Cloud Storage bucket. You can do this by running the configuration commands below in Cloud Shell, or by editing the files directly in Cloud Shell Editor.
Method 1: Automated Configuration via Terminal (Recommended)
Run the following commands in Cloud Shell to update the project ID, bucket name, and region across both scripts:
sed -i "s/PROJECT_ID = .*/PROJECT_ID = \"${PROJECT_ID}\"/g" ~/esports/esports-simulation.py
sed -i "s/PROJECT_ID = .*/PROJECT_ID = \"${PROJECT_ID}\"/g" ~/esports/esports-pipeline.py
sed -i "s|GCS_TEMP_LOCATION = .*|GCS_TEMP_LOCATION = \"gs://${BUCKET_NAME}/temp\"|g" ~/esports/esports-pipeline.py
sed -i "s/REGION = .*/REGION = \"${REGION}\"/g" ~/esports/esports-pipeline.py
Method 2: Manual Configuration via Cloud Shell Editor
If you prefer to edit the files manually:
- Click Open Editor in the Cloud Shell toolbar.
- In the Explorer pane, expand the
esports folder.
- Open
esports-pipeline.py:
- Set
PROJECT_ID (around line 11) to <ql-variable key="project_0.project_id" placeHolder="Project ID"></ql-variable>.
- Set
GCS_TEMP_LOCATION (around line 18) to gs://<ql-variable key="project_0.project_id" placeHolder="Project ID"></ql-variable>-bucket/temp.
- Set
REGION (around line 19) to <ql-variable key="project_0.default_region" placeHolder="Region"></ql-variable>.
- Save the file (File > Save).
- Open
esports-simulation.py:
- Set
PROJECT_ID (around line 10) to <ql-variable key="project_0.project_id" placeHolder="Project ID"></ql-variable>.
- Save the file (File > Save).
Save configured files to Cloud Storage
Copy your configured scripts to your lab's Cloud Storage bucket to verify your setup:
gcloud storage cp ~/esports/esports-simulation.py gs://${BUCKET_NAME}/esports/
gcloud storage cp ~/esports/esports-pipeline.py gs://${BUCKET_NAME}/esports/
Click Check my progress to verify the objective.
Retrieve the Python files and configure them
Task 4. Generate synthetic data and run the pipeline
In this task, you will run the Python files to generate the synthetic data and run the pipeline.
Install the dependencies and run the simulator
-
Return to Cloud Shell terminal.
-
Confirm you are in the home directory.
cd ~
-
Navigate to the esports directory.
cd esports
-
Use pip to install the dependencies, specifically the Python library for Pub/Sub.
pip install google-cloud-pubsub
-
Run the simulator. This script will run continuously, sending events to your Pub/Sub topic.
python3 esports-simulation.py
You will see output indicating that events are being published in the terminal. Keep this terminal open and running.
Confirm messages are published to the topic in the Pub/Sub console
-
Use the search function at the top of the console. This time, search for Pub/Sub, and click Pub/Sub in the list.
-
Click on esports_events_topic, which is the topic ID. You see the Subscriptions tab appear for the topic, and the esports_events_topic-sub subscription is listed.
-
Click on esports_events_topic-sub, which is the Subscription ID.
-
On the esports_events_topic-sub subscription detail page, click on the MESSAGES tab. You see a message indicating, "Click Pull to view messages and temporarily delay message delivery to other subscribers."
-
Click PULL. If you see messages listed here, this confirms that messages generated by the esports-simulation.py file are being received by Pub/Sub. Feel free to explore one of the messages, using the view contents button.
Attempt to Run the Dataflow pipeline
-
Open a new Cloud Shell tab. Click the + icon on the Cloud Shell terminal bar to open a second terminal.
-
Confirm you are in the home directory.
cd ~
-
Navigate to the esports directory.
cd esports
-
Install the Python Dependencies for Dataflow (apache-beam). In the new terminal, set up a virtual environment and install the required libraries.
python3 -m venv df-env
source df-env/bin/activate
pip install apache-beam[gcp]
-
Attempt to launch the Dataflow pipeline. Run the pipeline script using the command below. Make sure you've set your PROJECT_ID and BUCKET_NAME environment variables in this new terminal as well.
export PROJECT_ID="{{{project_0.project_id|set at lab start}}}"
export BUCKET_NAME="{{{project_0.project_id|set at lab start}}}-bucket"
python3 esports-pipeline.py \
--project=$PROJECT_ID \
--region={{{project_0.default_region | Region}}} \
--runner=DataflowRunner \
--streaming \
--temp_location=gs://$BUCKET_NAME/temp \
--job_name=esports-leaderboard-pipeline \
--worker_machine_type=e2-standard-2
This command submits the job to the Dataflow service. It will take a few minutes for the job to start up and begin processing data.
However, at this point you will see a warning and an errors like these below:
WARNING:apache_beam.options.pipeline_options:Bucket specified in staging_location has soft-delete policy enabled. To avoid being billed for unnecessary storage costs, turn off the soft delete feature on buckets that your Dataflow jobs use for temporary and staging storage. For more information, see https://cloud.google.com/storage/docs/use-soft-delete#remove-soft-delete-policy.
ERROR:apache_beam.runners.dataflow.dataflow_runner:2025-07-11T14:50:27.572Z: JOB_MESSAGE_ERROR: The Dataflow service agent cannot access the worker service account. Ensure that the Dataflow API is enabled for your project. In addition, verify that for the worker service account, the Dataflow service agent principal has the 'Cloud Dataflow Service Agent' role. To grant the role, see https://cloud.google.com/iam/docs/manage-access-service-accounts#view-access. On the Service Accounts page, select the worker service account, open the Permissions tab, and select 'Include Google-provided role grants' to verify roles. To learn more about service accounts, see https://cloud.google.com/dataflow/docs/concepts/security-and-permissions#permissions
What do these mean? First, let's start with the WARNING.
The warning indicates that the bucket used in this lab, -bucket, must have the Soft Delete protection feature disabled. We recommend you disable it, and we will provide instuctions below to disable it.
Regarding the ERROR... Now, let's address the ERROR... What does it mean?
There are two possible causes for this error:
-
The Dataflow API is not enabled. However, at the launch of your lab, we enabled this for you. You can confirm this by going to APIs & Services.
-
The actual cause of the error is that the Dataflow Service Agent principal needs permission to access the worker service account. Specifically, the Dataflow Service Agent requires the Cloud Dataflow Service Agent role on the Compute Engine default service account. Below, we will include instructions to complete this task.
Disabling Soft Delete feature on the Cloud Storage bucket
-
Use the search function at the top of the console. Search for Cloud Storage, and click the Cloud Storage option in the list. You see the Overview page appears.
-
Click Buckets. You see the Buckets page appears and your bucket, -bucket is displayed in the list.
-
Click on -bucket. You see the details page appears for the bucket.
-
Click on Protection. You see a list of options appears, with Soft delete policy (for data recovery) included.
-
Click Disable. You see a pop-up appears for Disable soft delete policy.
-
Click Confirm. Soft delete policy is now disabled.
Adding the required Dataflow permissions
To grant the Dataflow Service Agent and worker service account all necessary permissions to launch and manage the pipeline:
-
In Cloud Shell (or in your terminal tab), run the following commands:
export PROJECT_ID="{{{project_0.project_id|set at lab start}}}"
export PROJECT_NUMBER=$(gcloud projects describe {{{project_0.project_id|set at lab start}}} --format="value(projectNumber)")
# 1. Ensure Dataflow Service Agent identity exists and has project-level role
gcloud beta services identity create --service=dataflow.googleapis.com --project=$PROJECT_ID
gcloud projects add-iam-policy-binding $PROJECT_ID \
--member="serviceAccount:service-${PROJECT_NUMBER}@dataflow-service-producer-prod.iam.gserviceaccount.com" \
--role="roles/dataflow.serviceAgent" \
--condition=None
# 2. Compute Engine worker service account binding is pre-configured by lab setup
gcloud iam service-accounts add-iam-policy-binding \
${PROJECT_NUMBER}-compute@developer.gserviceaccount.com \
--member="serviceAccount:service-${PROJECT_NUMBER}@dataflow-service-producer-prod.iam.gserviceaccount.com" \
--role="roles/dataflow.serviceAgent" 2>/dev/null || true
# 3. Ensure Compute Engine worker service account has Dataflow Worker role
gcloud projects add-iam-policy-binding $PROJECT_ID \
--member="serviceAccount:${PROJECT_NUMBER}-compute@developer.gserviceaccount.com" \
--role="roles/dataflow.worker" \
--condition=None
Run the Dataflow pipeline
-
Return to Cloud Shell.
-
Confirm you are on the second terminal tab, the one for running the Dataflow pipeline (esports-pipeline.py).
-
Run the following command, once again.
export PROJECT_ID="{{{project_0.project_id|set at lab start}}}"
export BUCKET_NAME="{{{project_0.project_id|set at lab start}}}-bucket"
python3 esports-pipeline.py \
--project=$PROJECT_ID \
--region={{{project_0.default_region | Region}}} \
--runner=DataflowRunner \
--streaming \
--temp_location=gs://$BUCKET_NAME/temp \
--job_name=esports-leaderboard-pipeline \
--worker_machine_type=e2-standard-2
This time you should see a message indicating, "Autoscaling is enabled for Dataflow Streaming Engine. Workers will scale between 1 and 100 unless maxNumWorkers is specified."
This means that you have overcome the soft delete warning, and the Cloud Dataflow Service Agent error.
Access the Dataflow Service and observe the Pipeline
-
Use the search function at the top of the console to search for and select the Dataflow service. You see the Jobs page appears, with two Jobs of the same name. One is running and the other failed.
-
Click on the running job. You see the job graph appears. At the bottom of the page, you see the Logs pane.
-
Expand the Logs pane. You see tabs for JOB LOGS and WORKER LOGS.
-
Click WORKER LOGS.
-
Review the logs provided here. If you see logs for indicating the raw_events, player_score_updates and/or team_score_updates tables created, you can move on to the next task.
Note: It may take 5 to 7 minutes to see these logs for the tables being created.
Click Check my progress to verify the objective.
Generate synthetic data and run the pipeline
Task 5. Verify the results in BigQuery
In this task, you will run SQL queries to verify the results of the processed messages. To accomplish this, you will create two views, and then query the views to display the player and team leaderboards. You will also take time to reflect on how Looker could be used to enhance the leaderboard visualizations.
Create the views in BigQuery
-
Return to BigQuery.
-
In the explorer, expand your project and select the esports_analytics dataset.
-
Click the + (plus) to create a new query.
-
In the query tab provided, enter the following query.
-- Query 1: Create the Player Leaderboard View
-- This view finds the most recent score for each player and ranks them.
CREATE OR REPLACE VIEW `esports_analytics.player_leaderboard_live` AS
SELECT
-- Use the RANK() window function to calculate the rank in real-time
RANK() OVER (ORDER BY total_score DESC) as rank,
player_id,
total_score,
last_updated
FROM (
-- This subquery gets only the single most recent score for each player
SELECT
player_id,
total_score,
last_updated,
ROW_NUMBER() OVER (PARTITION BY player_id ORDER BY last_updated DESC) as rn
FROM
`esports_analytics.player_score_updates`
)
WHERE rn = 1;
-- Query 2: Create the Team Leaderboard View
-- This view finds the most recent score for each team and ranks them.
CREATE OR REPLACE VIEW `esports_analytics.team_leaderboard_live` AS
SELECT
-- Use the RANK() window function to calculate the rank in real-time
RANK() OVER (ORDER BY total_wins DESC) as rank,
team_id,
total_wins,
last_updated
FROM (
-- This subquery gets only the single most recent score for each team
SELECT
team_id,
total_wins,
last_updated,
ROW_NUMBER() OVER (PARTITION BY team_id ORDER BY last_updated DESC) as rn
FROM
`esports_analytics.team_score_updates`
)
WHERE rn = 1;
This query creates two views: one for the player leaderboard and the other for the team leaderboard. It will find the most recent scores for the player and the team, and rank them accordingly.
Run a query to display the player leaderboard
-
Click the plus to create a new query.
-
In the query tab provided, enter the following query.
SELECT * FROM `esports_analytics.player_leaderboard_live` ORDER BY rank;
Run a query to display the team leadeboard
-
Click the plus to create a new query.
-
In the query tab provided, enter the following query.
SELECT * FROM `esports_analytics.team_leaderboard_live` ORDER BY rank;
Time to reflect
Using your journal, answer the following questions:
- Which player is currently in the lead?
- Which team is currently in the lead?
Click Check my progress to verify the objective.
Verify the results in BigQuery
Congratulations!
You have generated Google Cloud resources to support your esports Dataflow pipeline, including a Pub/Sub topic and subscription, a BigQuery dataset, tables, and views, and the pipeline itself using simulated streaming data generated from Python scripts. You are becoming more confident with Google Cloud each day and can use Pub/Sub, Dataflow, and BigQuery to build and operate scalable streaming data pipelines.
Next steps / learn more
Google Cloud training and certification
...helps you make the most of Google Cloud technologies. Our classes include technical skills and best practices to help you get up to speed quickly and continue your learning journey. We offer fundamental to advanced level training, with on-demand, live, and virtual options to suit your busy schedule. Certifications help you validate and prove your skill and expertise in Google Cloud technologies.
Manual last updated on October 15, 2026
Lab last tested on October 15, 2026
Copyright 2026 Google LLC. All rights reserved. Google and the Google logo are trademarks of Google LLC. All other company and product names may be trademarks of the respective companies with which they are associated.








